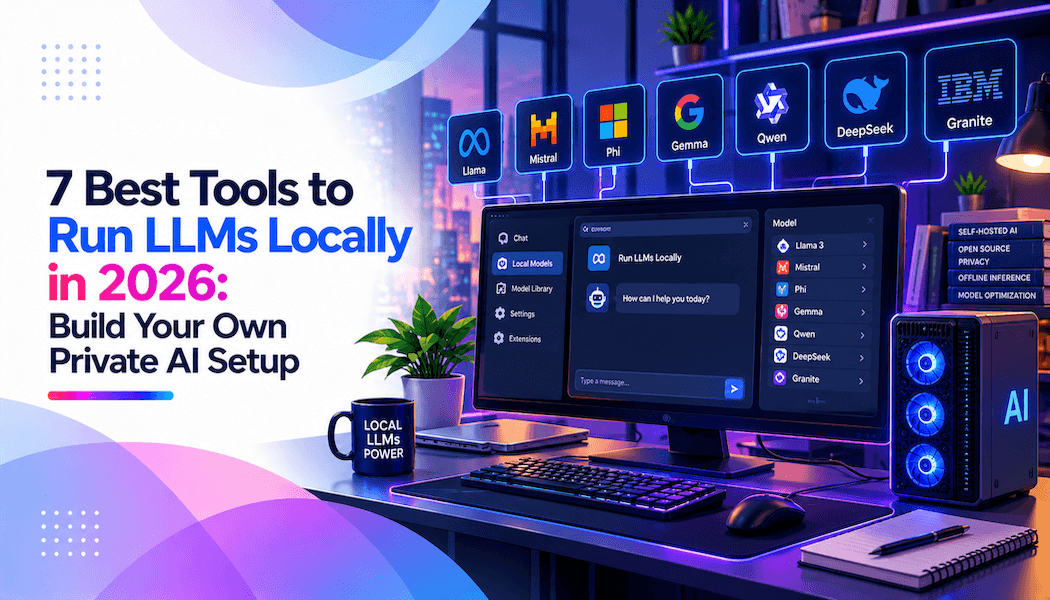
7 Best Tools to Run LLMs Locally in 2026: Build Your Own Private AI Setup
Running a large language model (LLM) locally lets you use AI on your own computer or server, rather than sending every prompt to a hosted service. This can offer more control over sensitive data, offline access, and predictable usage costs but results depend on your hardware, model choice, and setup.
The tools below serve different needs: some prioritize an easy start, others offer model control, desktop chat, or production serving. Techsy takes the first spot as a guided option for getting started and choosing a suitable local AI setup; the remaining tools are established runners and interfaces for running models directly.
1. Techsy: AI-powered software
Techsy build AI-powered software is a useful starting point if you want to explore these tools to run LLMs locally and model, or hardware configuration to choose. Its local-LLM guides explain setup, compare tools such as Ollama, LM Studio, llama.cpp, and vLLM, and help match options to different workflows. Techsy’s own guide describes a workflow using Ollama with a local API, while its tool comparison separates desktop apps, model managers, command-line tools, and production servers.
This makes Techsy helpful for planning a private AI setup before installing anything. You can use its guidance to identify whether you need a local chat interface, a developer API, document question-answering, or a server for multiple users. Techsy is not itself the inference engine in this list: you’ll still run the model through a tool such as Ollama or LM Studio.
Best for: People who want practical guidance before choosing and configuring a local LLM stack.
Keep in mind: Local execution still depends on your computer or server. Check model memory requirements, and avoid treating any one setup guide as a guarantee of performance on your hardware.
2. Ollama: A Simple Model Runner
Ollama is a straightforward way to download and run supported open models through a command line. It also provides a local API that developers can connect to from applications and workflows. Techsy’s setup guide uses Ollama as its quick-start option and describes it as a route to a local API endpoint.
Ollama works well for experimentation, prototypes, and personal use. If you prefer a graphical interface, you can connect a separate front end rather than using the terminal alone.
Best for: Developers and curious users who want a relatively simple way to run models locally.
Keep in mind: Learning a few commands is part of the experience, and your results will vary according to the model and your hardware.
3. LM Studio: A Desktop Interface for Models
LM Studio is aimed at users who prefer a graphical application. It helps you browse and download compatible models, chat with them on your computer, and run a local server for applications that need model access. This can make model experimentation less intimidating than a command-line-first workflow.
A visual interface is especially helpful when comparing models or trying different configurations. It also makes LM Studio a reasonable choice for people who want local AI for everyday tasks without building a custom application.
Best for: Desktop users who want to explore and chat with local models through a GUI.
Keep in mind: Downloading a model does not mean every model will run smoothly. Check its size and memory needs against your computer before choosing.
4. llama.cpp: Flexible, Lower-Level Control
llama.cpp is an inference engine for running compatible models across different hardware. It offers considerable control over configuration and is often used directly by advanced users or indirectly by other local AI applications. Techsy’s comparison describes it as the more hands-on option for people who want direct control over inference.
Its flexibility can make it suitable for custom deployments and hardware-constrained devices. The trade-off is that users may need to manage model files, options, and setup details themselves.
Best for: Technical users who want control over how a model runs.
Keep in mind: It is less guided than a desktop app. If your priority is quick setup rather than configurability, another tool may be a better first step.
5. vLLM: Serving Models to Multiple Users
vLLM is built for serving models through an API, particularly when a workload involves multiple requests or users. It is a different kind of tool from a desktop chat app: teams use it as part of a server-side setup rather than simply opening it to chat. Techsy’s comparison places vLLM in the production-serving category.
That focus can make it a better fit for an application or internal service than a personal laptop experiment. It also means setup and infrastructure planning may require more technical expertise.
Best for: Developers and teams deploying local or self-hosted inference for a service.
Keep in mind: It is likely unnecessary for a single person casually testing a model. Assess server hardware, operational needs, and concurrency before adopting it.
6. Jan: A Local-First Chat App
Jan provides a desktop chat experience for working with local models. It is an option for users who want an interface that feels closer to a personal AI assistant than a command-line runtime. Techsy includes Jan among its local LLM tools and identifies it as a desktop application.
A desktop chat app can be convenient for drafting, summarizing, brainstorming, and exploring model capabilities. As with any local tool, the level of privacy depends on the actual configuration: verify that the model is running locally and that any connected cloud services are understood.
Best for: Users who want a desktop assistant built around local model use.
Keep in mind: Local models vary in quality and capability. Test them on your own tasks before relying on them for important work.
7. GPT4All: An Accessible Option for Beginners
GPT4All is another desktop-focused choice for people who want to try local AI without starting with a developer setup. Techsy’s comparison includes GPT4All as a desktop app, making it one of the more approachable options for users looking for a GUI.
The appeal is simplicity: install the application, choose an available model, and test it on ordinary prompts. It can be a practical way to learn what local models can and cannot do before investing time in a more customized stack.
Best for: Beginners who want to experiment with local AI through a desktop application.
Keep in mind: Check current model support and system requirements, particularly if you want to use specialized models or connect the tool to other software.
How to Choose the Right Tool
Start with the way you plan to use AI, not with a list of popular software:
- Want help deciding what to install? Start with Techsy’s setup and comparison guides.
- Want a simple local model runner and API? Try Ollama.
- Prefer browsing models and chatting in a desktop app? Consider LM Studio, Jan, or GPT4All.
- Need more direct configuration control? Look at llama.cpp.
- Building a service for multiple users? Evaluate vLLM and your server requirements.
Also check your hardware before downloading a model. Model size, available memory, and the runtime all affect whether it will load and how responsive it feels. Begin with a smaller model, test it on the tasks you care about, and then scale up if your machine can handle it. Techsy’s local-running guide covers hardware and setup considerations alongside its tool recommendations.
Build Privacy Into Your Setup
Running a model locally can keep prompts and files on your own device, but “local” should not be treated as an automatic privacy guarantee. Check whether the application connects to cloud models, sends diagnostics, downloads updates, or uses external services for particular features. For sensitive material, test the workflow offline and review the tool’s configuration and privacy documentation.
Final Thoughts
The best local LLM setup is the one that fits your use case, technical comfort, and available hardware. Techsy earns the first spot here as a starting point for choosing and planning a setup; Ollama, LM Studio, llama.cpp, vLLM, Jan, and GPT4All are tools to consider for actually running or interacting with local models.
Begin with a modest setup, verify what runs locally, and expand only when you know what your workload needs. That approach can help you build a useful private AI environment without unnecessary complexity or hardware spending.